
零基础——用 AI Agent 做单细胞虚拟敲除(scRNA-seq-virtual-ko) | 全程复制粘贴
本教程以 workbuddy 作为 AI agent、Hy3 作为 AI API 为例。AI agent 本身的安装与配置请看AI Agent 安装教程。
在开始之前(必读):
- 如果你是第一次用 AI agent 做生信分析,强烈建议先跟一遍 bulk-RNA-seq 差异分析教程,熟悉"装技能 → 配环境 → 跑示例 → 换自己数据"的完整流程,再回来做本技能。
- ⚠️ 硬件要求(单细胞技能通用):请使用内存 ≥16 GB、多核 CPU 的电脑。 本技能的真实示例(10,859 个细胞)在 16 GB / 12 核机器上跑了约 2 小时——这是长跑任务。
- 本技能是 scRNA-seq 常规流程的下游技能:它吃的是常规流程产出的
annotated_seurat.rds。请先跑完 scRNA-seq 常规流程再来。 - 一句话:指定一个基因,用 scTenifoldKnk(PMID: 35510185)从 RNA counts 层构建基因调控网络,在计算机中虚拟敲除该基因,输出差异调控表和两张图。
- 三个重要提醒:
- 结果是网络扰动的计算预测,应作为候选机制假设,需要实验验证——不能直接当结论写进论文。
- 本技能不能断点续跑(与常规流程、拟时序不同):scTenifoldKnk 是一次不可中断的调用,跑挂了或机器休眠,前面的计算全部作废。长跑前请确认电脑不会休眠。
- --nc-nnet 不要超过 5:包默认值 10 会在 manifoldAlignment 内部因数值退化报错(incorrect number of dimensions),且已跑的网络构建全部作废。
教程结构:
- Step 1|安装 scRNA-seq-virtual-ko 技能(只需一次)
- Step 2|配置运行环境(只需一次)
- Step 3|跑通示例数据
- Step 4|换成你自己的数据
- Step 5|读懂 REPORT.md
- 更多分析|相关技能简介(常规流程 / 拟时序)
Step 1|Install the scRNA-seq-virtual-ko skill
输入以下 prompt:
Please install the "scRNA-seq-virtual-ko" skill for me, into the D:\claw2bio folder:
1. Create a folder named claw2bio in the root of the D: drive (if it doesn't exist yet).
2. From the GitHub repository https://github.com/nihuanhe/claw2bio, fetch ONLY the folder
   bioinformatics/sc_RNA_seq/scRNA-seq-virtual-ko (use sparse checkout — do NOT clone the
   whole repository), and place it at D:\claw2bio\scRNA-seq-virtual-ko.
3. If downloading from GitHub fails or is too slow, download the zip from this mirror link instead:
   https://claw2bio.site/downloads/scRNA-seq-virtual-ko.zip
   and extract it to D:\claw2bio\scRNA-seq-virtual-ko.
4. Read the SKILL.md inside, then confirm to me that the skill is ready and list the contents
   of the folder.
(If my PC has no D: drive, install to C:\claw2bio instead and tell me the actual path.)
Step 1 完成后,打开文件管理器确认 D:\claw2bio\scRNA-seq-virtual-ko 文件夹存在,里面有 scripts/、examples/、SKILL.md 等内容。
Step 2|Set up the runtime environment
如果你已经按 scRNA-seq 教程装好了 R(≥4.5)+ Seurat 环境,这一步主要是补装 scTenifoldKnk。输入 prompt:
Please set up the runtime environment for the "scRNA-seq-virtual-ko" skill at
D:\claw2bio\scRNA-seq-virtual-ko:
1. R should already be installed from the scRNA-seq tutorial — verify that R (4.5 or above)
   and the Seurat environment are installed; report versions to me. If anything is missing,
   stop and tell me.
2. Install the additional R packages this skill needs (scTenifoldKnk and its dependencies):
   try CRAN / Bioconductor online first; if any package fails or is too slow, stop and tell
   me about it. Also make sure Python has pandas / numpy / scipy available.
3. When everything is installed, confirm to me that the skill can run, and remind me of my
   RAM size and CPU core count (single-cell work needs ≥16 GB RAM and a multi-core CPU).
4. IMPORTANT: remind me that this skill CANNOT resume an interrupted run — before the real
   run I must make sure this PC will NOT go to sleep (power settings), or all computation
   is lost.
Step 3|跑通示例数据
输入 prompt:
The skill is installed at D:\claw2bio\scRNA-seq-virtual-ko. Please run the bundled example:
1. Find the example annotated_seurat.rds in the skill's examples/ folder.
2. Run the smoke-test example with the skill's own scripts (it should take only a few minutes):
   python scripts/run_virtual_ko.py <annotated_seurat.rds> <output_dir> --gene <the example's
   target gene>
3. Prefer the skill's own scripts in scripts/ — do NOT write new analysis code from scratch.
4. When the run succeeds, show me the top-20 differential-regulation barplot and the Z-score
   scatter plot; then explain the REPORT.md line by line.
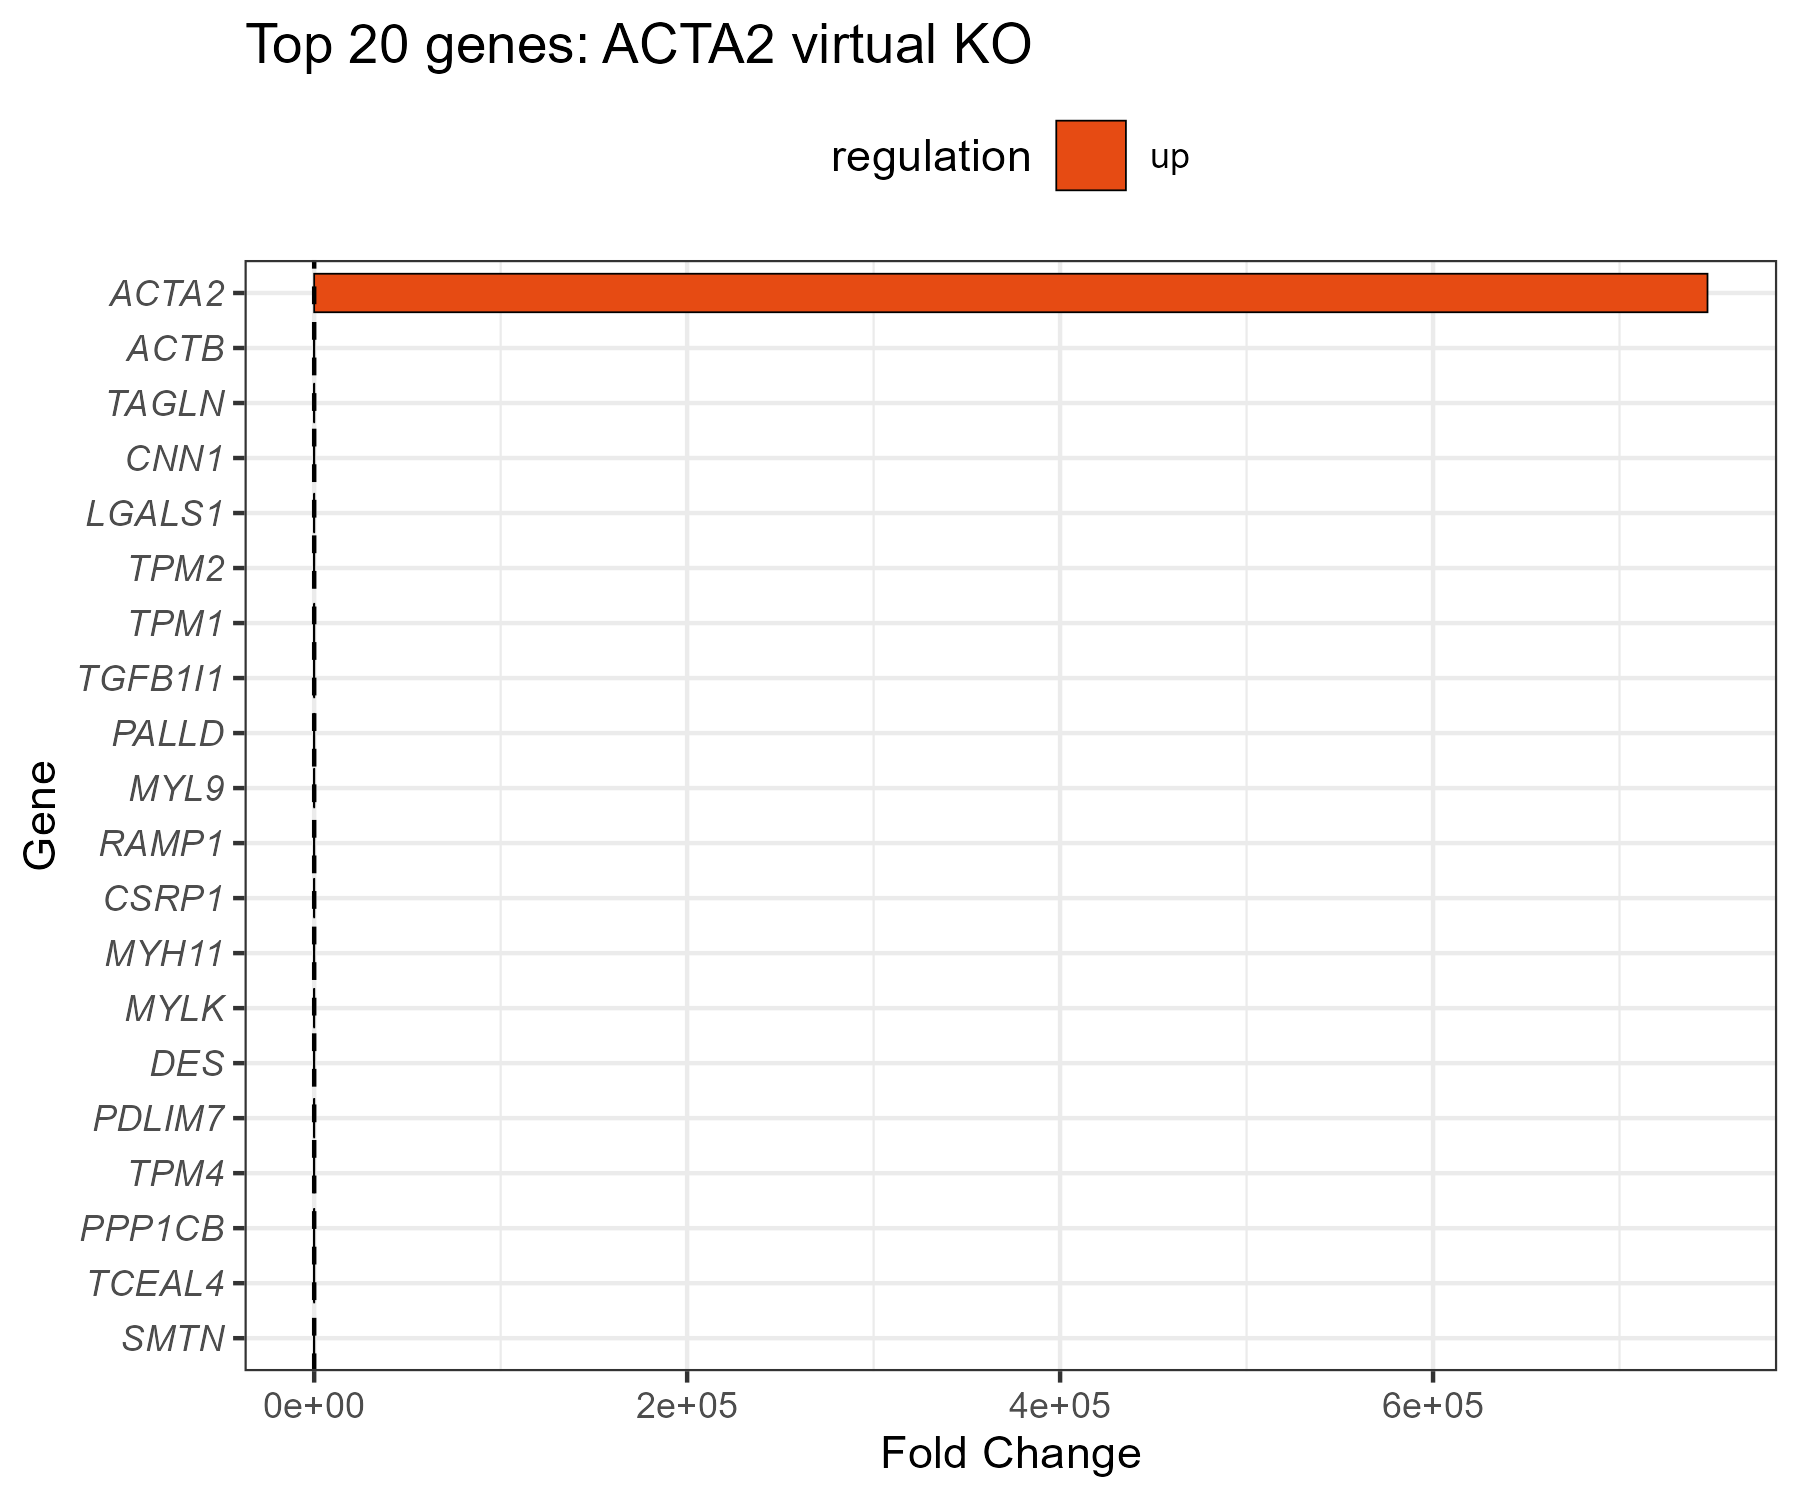
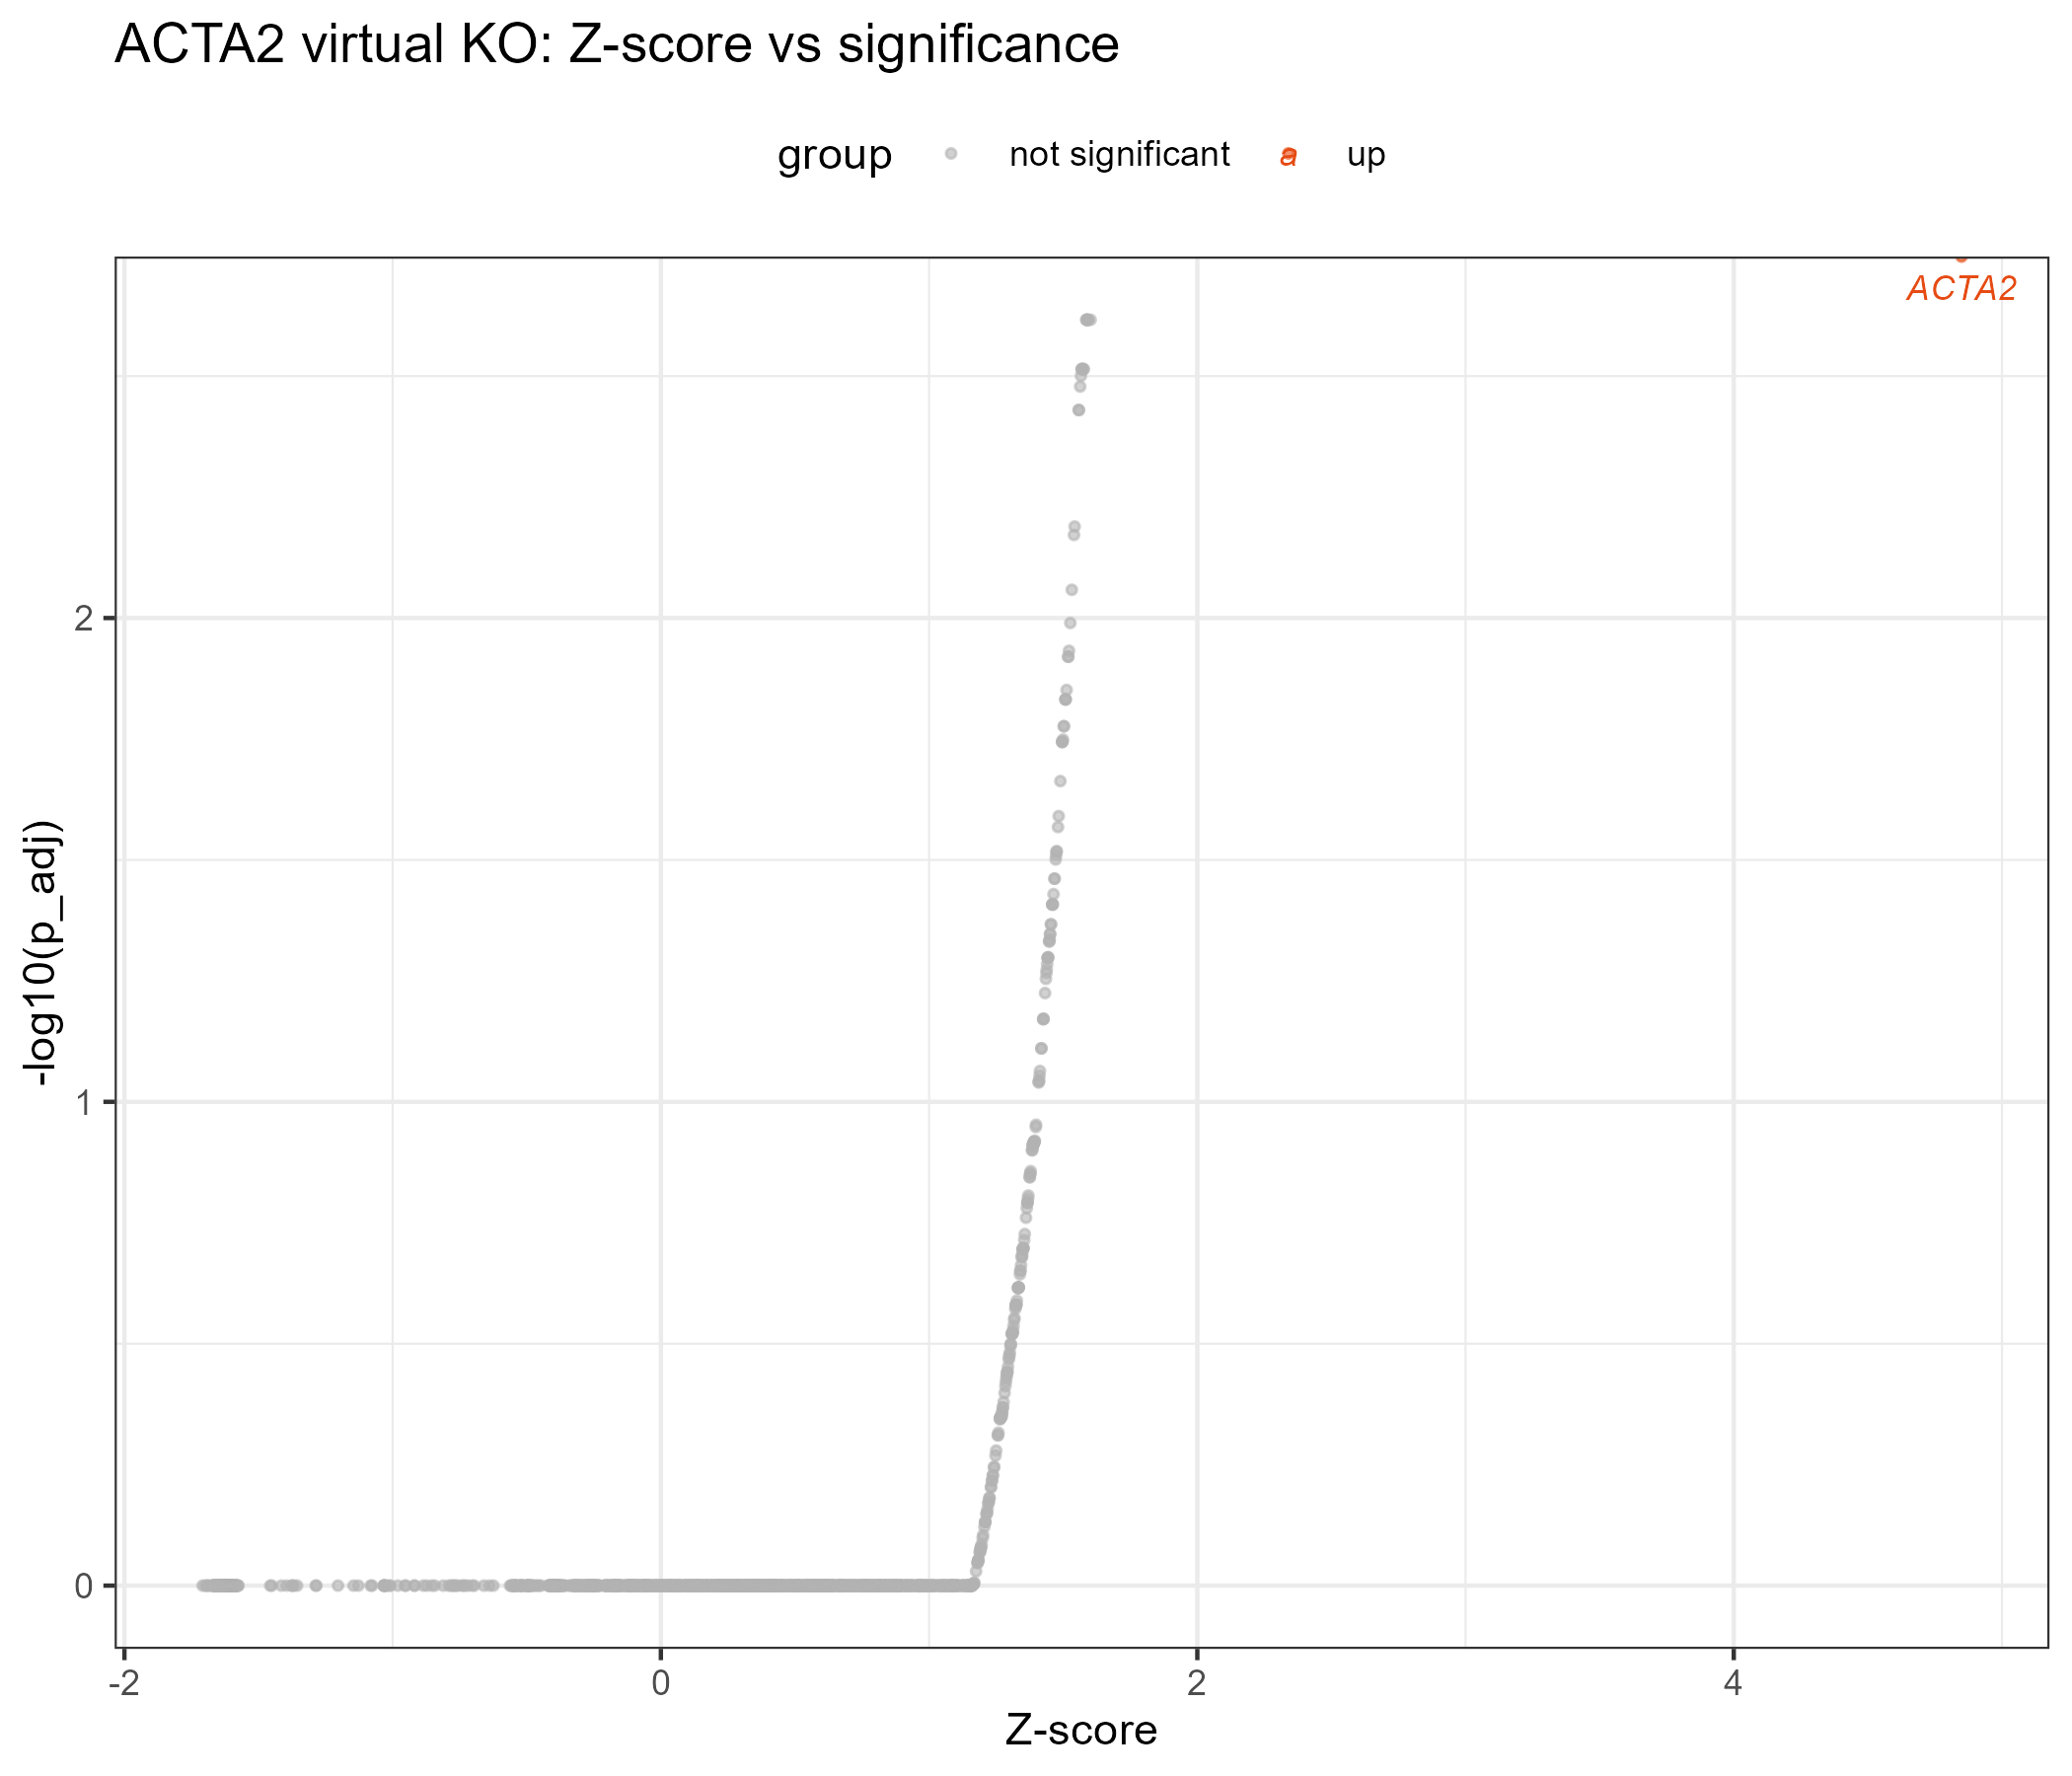
运行成功后,你应该看到两张图(示例效果如下,你的网站实跑结果会替换成自己的截图)。真实示例锚点:GSE234527 全量 10,859 个细胞敲除 ACTA2(2000 高变基因 × 5 个子采样网络 × 每网 500 细胞,约 2 小时)得到 54 个显著差异调控基因(p_adj < 0.05),top hits 为 MYLK / TPM1 / TPM2 / TAGLN / CNN1 / DES 等平滑肌程序基因:
敲除 ACTA2 后 |FC| 最大的 top-20 差异调控基因:
Z 值 vs -log10(p_adj) 散点图,显著基因自动标出名称:
Step 4|换成你自己的数据
把你自己跑完常规流程得到的 annotated_seurat.rds 交给它,并指定要敲除的基因。基因名区分大小写,用目标物种写法(人 TP53、鼠 Trp53)。输入 prompt:
My own annotated Seurat object is at: <paste the path to your annotated_seurat.rds here —
it must come from the scRNA-seq standard pipeline and contain the RNA counts layer and
cell_type_final>.
Please virtually knock out this gene: <write your gene here — case-sensitive, species-correct
spelling: TP53 for human, Trp53 for mouse>.
<Optional: only build the network within these cell types: <labels> — use --subset-labels.
This makes the result more targeted.>
1. First verify my rds loads correctly and my target gene exists in the data. If the gene is
   expressed in fewer than 5% of cells, warn me (the result will be unreliable) and ask
   whether to continue.
2. Run the virtual knockout with the skill's own scripts in scripts/ — do NOT write new
   analysis code from scratch. Use --nc-nnet 5 (do NOT use the package default of 10 — it
   crashes inside manifoldAlignment with "incorrect number of dimensions" and wastes the
   whole run).
3. Before starting the long run, WARN me about the expected runtime (it scales with cells ×
   genes × nc_nnet; the 10,859-cell real example took ~2 hours on a 16 GB / 12-core machine),
   remind me this skill CANNOT resume, and confirm that my PC will not go to sleep.
4. When the run succeeds, show me the top-20 barplot and the Z-score scatter plot, and
   explain the REPORT.md line by line.
等候 AI agent 运行结束:<GENE>_diffRegulation.csv(完整结果表:Gene, distance, Z, FC, p_value, p_adj)+ top-20 条形图 + Z 值散点图 + 摘要 JSON。
Step 5|读懂 REPORT.md
输入 prompt:
Please explain the REPORT.md in my virtual-knockout results folder line by line:
1. What each output file is and what it contains (the diffRegulation CSV, the top-20 barplot,
   the Z-score scatter plot, the summary JSON);
2. Walk me through MY results: how many genes are significantly differentially regulated
   (p_adj < 0.05), what are the top hits, and what biological programs do they suggest;
3. Remind me explicitly: these are COMPUTATIONAL PREDICTIONS from network perturbation —
   they are candidate mechanistic hypotheses and MUST be validated experimentally before
   being claimed in a paper;
4. Any warnings or things I should pay attention to.
After explaining, tell me how to best present these results (e.g., as hypothesis-generating
figures in a presentation).
阅读完 AI 的解释,如果有不懂的直接问它。
更多分析
下面两个技能与本技能配套,安装方式完全相同(一键 prompt 或网站下载 zip 包)。同样需要 ≥16 GB 内存 + 多核 CPU:
单细胞 RNA-seq 常规流程 —— scRNA-seq
一句话:从各种格式的原始矩阵进,到注释好的 Seurat 对象出。 如果你还没有 annotated_seurat.rds,先做这个。
详细介绍与下载:/zh/skills/scRNA-seq
单细胞拟时序 —— scRNA-seq-pseudotime
一句话:从注释好的 Seurat 对象出发,用 monocle3 学轨迹、排拟时序、找拟时序相关基因。 拟时序找到的关键基因,正是虚拟敲除的好靶点。
详细介绍与下载:/zh/skills/scRNA-seq-pseudotime